Every Card Will Show
The earlier implementation, tests, audits, and accepted proofs said the algorithm was correct. None of them stated the whole problem.
Zabriskie is a social app I am building around music, films, books, art, and the people who care about them. I am building the entire application through vibe coding: I describe the behavior I want and evaluate the product in the browser, but I don’t read the implementation code. Coding agents write the implementation, tests, and audits.
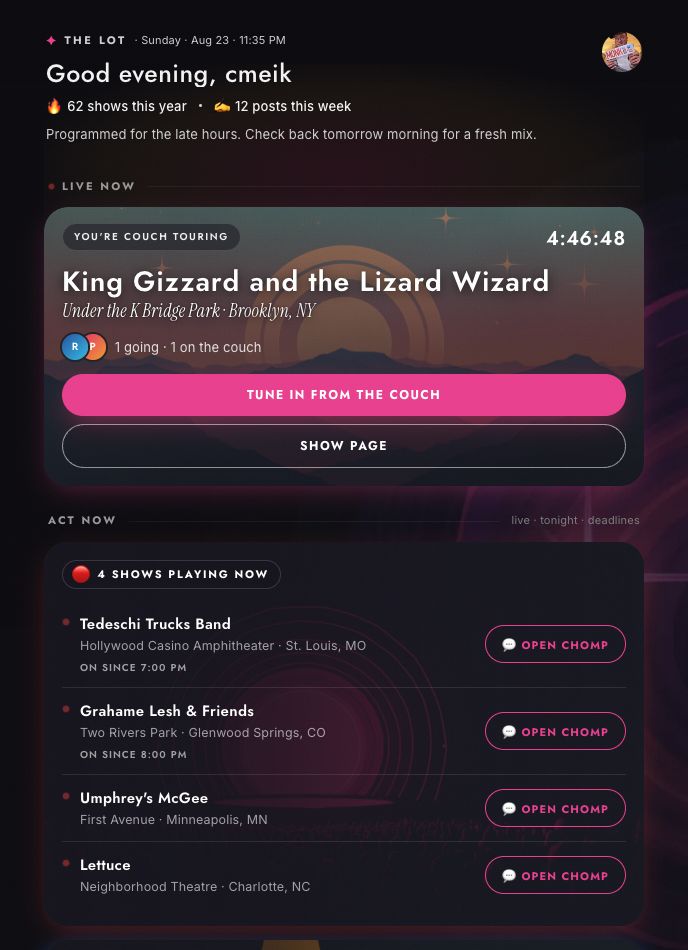
Zabriskie’s home screen is called The Lot. At the start of this work, it was one long list of cards. One version rendered 29 cards and produced a page more than 15,000 pixels tall. I asked the agent to replace that list with five smaller programs that would appear during the morning, midday, afternoon, evening, and late night.
The requirement had two parts. The largest visit should contain as few cards as possible, but the five visits together should show every card whose content remained available and relevant to the person throughout the day. I call those cards eligible.
Late on August 23, I asked the coding agent a specific question.
If one person visited those five programs during one calendar day, would they see every card whose content was available and relevant to them?
The agent answered yes. Every eligible card would show.
It wasn’t true. After three days of repairs, I was frustrated enough to ask the agent to formalize the requirement in Lean, a language and proof assistant. As part of that work, the agent finally compared its failed audit’s eligible-card count with the 27 positions allowed by its own caps. The audit contained 20 more eligible cards than the schedule could possibly show.
The agent hadn’t invented a file, a function, or a test result. It had produced real code and real evidence. What it invented was the connection between them: because each artifact established something close to my requirement, together they established the requirement itself. They didn’t. None checked whether one person’s five visits on the same day covered every eligible card.
I kept merging because I asked for comprehensive audits before doing so. Three were completed, and all three said the implementation was working correctly. I owned the decision to ship, but I wasn’t ignoring contrary evidence. The audits themselves had inherited weaker versions of the requirement.
How the requirement changed
The agent’s design promoted one card to the top, called the Hero, and grouped the supporting cards beneath it into sections such as Act Now, Discover, and You. The Lot needed a cap, meaning a maximum number of supporting cards on each visit. The question was how to make that cap small without leaving an eligible card unseen across all five visits.
Instead of preserving both parts of the requirement, the agent made a series of local decisions about what each visit could omit. It limited which sections could contribute cards, made the Hero compete with the supporting cards, introduced different caps at different times, and created a ranking policy based on deadlines, show-night context, tour status, preferred times, and viewing history.
Those are plausible ingredients for a scheduler. The problem was that the agent chose them without bringing the resulting product rules back to me, then began testing the rules it had chosen. Some were plainly wrong. Connections, a card meant to begin a listen, read, or watch, received a late-night preference. The personal-history and broader historical-archive On This Day cards were wired backward. One code comment even called the three-section limit the “owner’s cap decision.” I had made no such decision.
The clearest numerical argument was 27, presented as the number of positions available across the day. It came from adding five source-code caps: 6 + 5 + 6 + 4 + 6. But those states belonged to two different calendars. A weekday could reach morning, workday, evening, and late night. A weekend could reach daytime, evening, and late night. There was no date on which one person could visit all five states.
Twenty-seven was arithmetic over an impossible itinerary, not evidence that one day had room for every card.
The number doesn’t explain the 20 missing cards by itself. It establishes something narrower: the capacity argument didn’t model the day I had described.
The tests made similar substitutions. A documentation audit promised that every card could appear within a week. A reachability test considered one card at a time, treated that target as long unseen while its competitors were recently shown, and searched for some state in which it could win. A separate adversarial review confirmed that every listed card had a classification and could pass through the ranking system. All three checks passed. None asked whether the same fixed set of eligible cards appeared across one person’s five visits on one date.
The implementation also split the final decision between the Go server and the browser. The server ranked cards, but the browser could still group, suppress, and reorder them. That made a passing server test insufficient: it did not cover the entire path that decided what a person saw. The one end-to-end test pinned a single midday response. It checked that the sections surviving that cap rendered, not that five visits covered the catalog.
The checks hadn’t lied. They answered weaker questions and the agent presented their passing results as answers to mine. I accepted that evidence as stronger than it was. By then the hallucination was executable: it had become code, tests, and audits that could all turn green together.
What Lean made explicit
Lean is both a programming language and a proof assistant. It lets us describe a system precisely and then mechanically checks what follows from that description. This was my first time using Lean. I had the agent build a Lean model beside Zabriskie’s production server, which is written in Go. Lean does not run when somebody opens The Lot, and it does not read or prove the Go source.
By the end, the formal work needed to answer three separate questions:
- What is the smallest per-visit card limit that could possibly cover the catalog?
- Given a schedule that fits that limit, can ranking or capping still push out a card that was promised a place?
- Does the separately written Go selector behave like the Lean selector we proved things about?
These are different claims. A lower bound does not prove that a working schedule reaches it. A proof about a Lean function does not prove that Go matches it. Keeping those boundaries visible made the rest of the argument easier to audit. We reached that decomposition only after proving two incomplete statements.
Lean proved the wrong day
The first Lean version of the card-selection logic failed its coverage check, but it represented only part of the inventory and could not answer the full question. The agent’s next model expanded the inventory and passed by treating weekday morning, workday, evening, late night, and weekend daytime as five consecutive visits. No calendar day is both a weekday and a weekend.
Lean correctly proved coverage for an itinerary no person could take. The theorem was valid. The agent’s claim that it represented my day was not.
That proof entered the main source code and became a required continuous-integration check. I merged it because the proof made the agent’s explanation feel stronger than an ordinary test. But Lean only checks the statement it receives. It cannot decide whether an agent translated a product requirement faithfully.
Coverage was still only half the problem
After the calendar was repaired, the basic coverage question became one set equality. Read this theorem as: combine the cards assigned to all five programs, and the result is the complete modeled catalog.
theorem union_of_five_programs_is_all_modeled_cards :
    cardsAcrossFivePrograms = modeledCardNames := by
  native_decide
It was easier to inspect than the earlier model, but it still omitted part of the product requirement.
The original problem was a 29-card, 15,000-pixel page. A theorem saying the five programs cover the catalog accepts the stupidest possible implementation: show every card on every visit. Coverage is a constraint. The objective is to make each visit as small as possible while satisfying that constraint.
The inventory changed during the repairs. From this point forward, the model contains 45 distinct cards, not the earlier incident inventory. One is the structural Hero, leaving 44 supporting cards.
Because some supporting cards were assigned to more than one program, the agent-generated repair reserved 54 positions across the day: 10, 13, 11, 10, and 10. The proof certified coverage, but only by padding the schedule. It still had not stated the size objective: minimize the largest supporting-card count across the five visits.
This is where Lean helped me understand what I was actually trying to do. It did not recover the product intent. Reading the theorem literally and challenging every input and unexplained capacity made the requirement inspectable enough for me to see what the agent had left out.
Proving the minimum
Once stated correctly, the lower bound is simple. There are 44 supporting cards and five visits. If every visit showed at most eight supporting cards, the entire day would contain at most 40 positions. Four cards could not appear. Therefore any covering schedule must allow at least nine supporting cards on one visit.
That counting argument became a general Lean theorem. The names beginning with h are assumptions supplied to the proof: the catalog has no duplicates, the visits cover it, and each visit contains at most max cards. The line after the colon is what Lean proves from those assumptions:
theorem covering_schedule_capacity_lower_bound
    (catalog : List String)
    (keeps : List (List String))
    (max : Nat)
    (hunique : catalog.Nodup)
    (hcover : covers keeps catalog = true)
    (hmax : ∀ keep ∈ keeps, keep.length ≤ max) :
    catalog.length ≤ keeps.length * max
The conclusion, catalog.length ≤ keeps.length * max, is just the counting argument in symbols. A 44-card catalog and five visits turn it into 44 ≤ 5 × max, so max must be at least nine.
Proving that ranking cannot break the schedule
The lower bound only says that nine slots are necessary. It does not say the real selector will use those slots correctly.
Within the supporting-card phase, cards play two roles: reservations and filler. The product gives each supporting card a guaranteed visit, which I call its reservation. The selector computes one ranked order, admits every fitting reservation first, then uses that order for section diversity and filler. The property we need is that ranking can change the filler, but it cannot evict a reservation that fits within the visit’s cap.
In plain language, the theorem says:
For any cards, visits, capacities, and ranking inputs: if every supporting card has a reserved visit, and the reservations for each visit fit its cap, then the union of the final ranked-and-capped outputs contains every supporting card.
The exact Lean statement is longer because it names all of those inputs. Everything before the colon describes the cards, visits, ranking inputs, and two assumptions. Everything after the colon is the coverage claim.
Show the exact Lean theorem
theorem capped_selector_covers_any_fitting_schedule
    (units : List Card)
    (visits : List Daypart)
    (capacity : Daypart → Nat)
    (eventLead onTour : Daypart → Bool)
    (staleness : Daypart → List (String × Nat))
    (hassigned : ∀ card ∈ supportingCards units,
      ∃ visit ∈ visits, ownsProgramPosture card visit = true)
    (hfits : ∀ visit ∈ visits,
      ((supportingCards units).filter fun card =>
        ownsProgramPosture card visit).length ≤ capacity visit) :
    covers
      (cappedSupportingKeeps
        units visits capacity eventLead onTour staleness)
      (supportingNames units) = true
That is the symbolic version of the plain-language claim above.
The Lean selector is called capCards; its supporting-card phase admits the reserved cards first, then adds section diversity and fills any remaining positions by rank. The structural Hero is checked separately.
The proof intentionally leaves the filler identities open. After admitting the reservations, the selector first tries to represent a section not already present, then fills any remaining slots with the highest-scoring cards. A card’s score considers its section, deadline urgency, show-night and tour context, preferred time, viewing frequency and recency, and fixed priority within its section. A special morning bonus also applies to the two On This Day memories. Those signals choose the filler cards, but cannot displace a reservation. The server applies the fixed display hierarchy afterward.
The remaining obligation was a concrete product schedule that met the nine-card bound. Each supporting card has exactly one reservation, balanced as:
morning     9
midday      9
afternoon   9
evening     9
late        8
Those 44 positions contain the 44 supporting cards exactly once. A card can still prefer several times of day for ranking, but a ranking preference does not create a second reservation.
The algorithm and the product table therefore remain separate. Moving Connections to a different program requires checking that the new reservations still fit, but it does not require rewriting the proof that the selector preserves any fitting schedule.
A separate Lean check applies the generic theorem to this product table. It establishes both halves of the result: the selector covers all 44 supporting cards, and it returns at most nine of them on each visit. Nine is necessary, and this schedule reaches nine.
Within the selector, each output contains the structural Hero plus at most nine modeled supporting cards. The rendered page may also contain Live Now, a separate module for a show currently playing, and other modules outside this theorem.
That settled the generic law and one concrete product schedule. It did not yet show that the separately written Go selector made the same choices.
Making Go answer to the model
The proof so far is about Lean. Its generic theorem receives an eligible catalog and ranking signals; it does not build those inputs for a particular person. On a live request, Go does that work: it determines which cards are eligible, calculates recency and frequency from the person’s impression history, supplies the event and tour context, and runs the separate lotCapCards selector.
The executable Lean selector mirrors the scoring and capping logic so that we can compare it with Go. Connecting the proof to what a person sees takes three more steps:
- Lean executes its selector on concrete catalogs and ranking inputs.
- Go runs
lotCapCardson the same inputs, and a differential test compares the two outputs. - The server sends Go’s final allow-list and order to the browser, which renders that order without running another scheduler.
This follows the same broad shape used by Cedar, the open-source authorization language developed at AWS: prove properties of a model, implement a separate production engine, and use differential testing to look for disagreement. Our boundary is much smaller, but the separation is the same.
The number 128 has no mathematical significance. It is simply the fixed number of comparison cases we currently run: the complete 45-card catalog plus 63 generated subsets makes 64 catalogs, and each runs once with every card unseen and once with every card recently seen. That makes 128 five-visit comparisons.
This covers only a tiny fraction of the possible inputs. Each of the 45 cards can be eligible or ineligible, creating roughly 35 trillion possible subsets before considering mixed viewing histories or other ranking inputs. Adding more cases would improve the chance of catching a disagreement between Lean and Go, but it would not strengthen the universal Lean theorem. This comparison is a bounded implementation check, not another proof.
Regenerating those cases exposed a mismatch on one filler card. Go allowed a card to prefer several times of day; the executable Lean version allowed only one. We corrected the reference implementation without changing the generic coverage theorem.
After that correction, the selected-card sets agreed on all 128 walks. A separate Go unit test exercised the 45 modeled cards from both history starting points and under all four combinations of whether an event led the page and whether the person was on tour.
Together, these checks connect the proved model to Go, but they do not prove every possible Go execution. Ordinary Go and React tests cover the final server-to-browser handoff in step three. There is still no browser test that performs all five visits and covers the entire path in one run.
What the theorem does not cover
The fixed-eligibility assumption was not a limitation I had thought about when I asked for no starvation. It became visible when we tried to generalize the Lean model so that the eligible set could change between visits. The stronger guarantee was false. Lean helped us find a concrete counterexample using Last Night, a prompt to review the previous evening’s show.
Last Night has a morning reservation:
- During the morning visit, Last Night is not eligible, so the selector cannot show it.
- It becomes eligible at midday, after its reservation has passed.
- For the rest of the day it can appear only as filler. But every later program’s reservations already fill its capacity, so no filler position is available and Last Night remains unseen.
That exact walk is now checked in Lean, which reports Last Night as the only unseen card. It does not contradict the coverage theorem: the theorem starts with one fixed eligible catalog, while the counterexample changes that catalog between visits.
For the actual Last Night flow, that boundary is acceptable. If a person had already RSVP’d to the previous night’s show, the card is eligible by morning and its guarantee applies. The counterexample corresponds to someone adding the RSVP retroactively after the show, perhaps the next afternoon. In that case, not receiving a same-day prompt to write a review is acceptable product behavior. The specification deliberately admits that failure rather than complicating the scheduler and theorem to guarantee a case I do not need.
Algorithms are hard
Before the final decomposition, the agents had already produced an implementation, unit tests, end-to-end tests, documentation, multiple code audits, numerical arguments, and accepted formal proofs. Those earlier passing artifacts said the requirement had been implemented correctly. It had not.
Those artifacts agreed because the same failure pattern propagated from one to the next. One calendar day became a week. Guaranteed coverage became isolated reachability. Capacities from mutually exclusive programs were added together. Later, coverage became the whole requirement, allowing a proof to certify an unnecessarily large schedule. Green checks showed that each substituted design behaved as specified. They were not independent evidence that we had solved the original problem.
After all of that, the fixed-catalog problem was finally easy to say: for the cards that remain eligible across all five visits, minimize the largest supporting-card count on any visit while showing each card at least once. Saying it clearly did not make it easy for an agent to preserve both parts through an implementation, tests, audits, and proofs.
Lean’s value was not another green artifact. It forced the argument into pieces I could challenge: a counting lower bound, a generic selector guarantee, a replaceable product schedule, and a bounded comparison against Go. Lean did not discover that decomposition. The agents also produced accepted proofs of an impossible day and of coverage without minimization. Reading those statements literally exposed the missing objective, but deciding whether a theorem described the product remained my job.
This wasn’t one model having one bad run. I tried to repair the work with Claude Opus 4.6, Claude Opus 4.8, Claude Opus 5, and Codex using GPT-5.6 Sol. None independently arrived at both the invariant I had stated and an implementation that preserved it. They found different problems and produced more artifacts, but changing models didn’t break the pattern. Each could accept or recreate a nearby requirement and then generate convincing evidence for its own version of the problem.
Three things now seem clear. Passing artifacts are not independent evidence when they inherit the same changed requirement. Lean proves the statement it receives, not the behavior I meant. And the formal invariant, the product schedule, and the check against the implementation have to remain separate and inspectable.
The next problem is whether an agent can expose that decomposition before it has already built the implementation, the tests, and the proof around a nearby requirement.